提问
从产品尚无法回答的问题出发。
Archymedes 实验室
实验室研究产品背后的问题:AI 何时该行动,它所知道的在实地是否成立,以及如何让它便宜到随处可用。我们公开方法、代码和局限。
方法
从产品尚无法回答的问题出发。
以真实情况为准,而不是看起来是否可信。
不合格的就放弃,无论多方便。
公开论文、代码、数据以及明确的局限。
研究方向
对于无人尝试过的事,AI 何时该行动?
Generative models are good at proposing options and bad at choosing between them. This line of work keeps the two apart: models judge, calibrated maths decides, and an uncertain option is checked against a fallback instead of being vetoed.
成果
它在实地成立吗?
Rebuilding real places as verified, lightweight 3D scenes from free public data. Every layer is registered against the best measurement available and its error is reported; a source that fails against the ground is dropped, however convenient.
成果
它能在普通硬件上运行吗?
Making capable models cheap enough to run where connections are slow or absent: compression and quantisation for small language models, and tooling that tunes GPU code without trading away correctness.
成果
论文
AI 何时该采纳一个无人尝试过的想法?不要直接否决,而是在保留退路的前提下先检验,并为检验可能漏掉的风险定价。
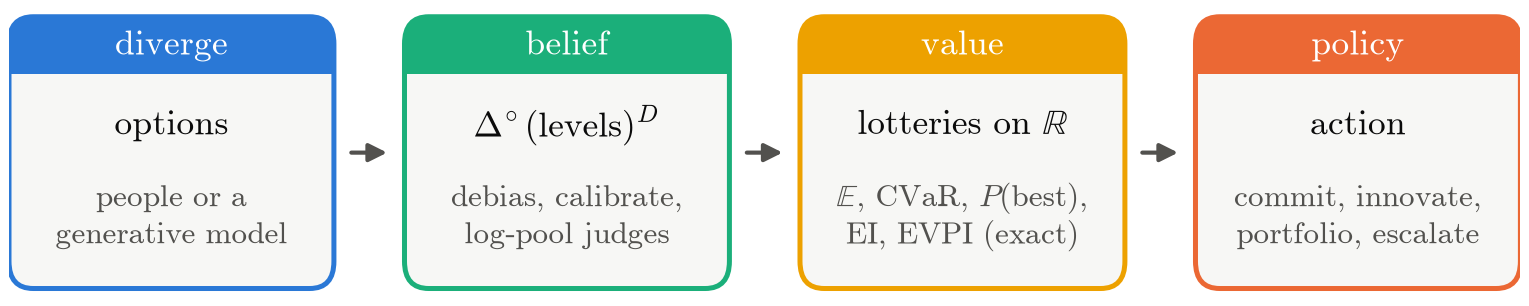
For a single decision, the value of a check depends on the belief about harm only through its mean. Ignorance and a known coin flip warrant the same action; the difference matters for learning across decisions.
On held-out synthetic problems, checking uncertain options halves the regret of vetoing them (0.045 vs. 0.091) at about 1% undetected harm, against 17–23% for acting on them unchecked.
Over 237 TypeSafe Jev judgments with known ground truth, Jev separates explicit harm from explicit safety almost perfectly (AUROC 0.9998), and cdm has the lowest regret and harm of the policies compared.
The gain comes from checking, not from the CVaR reliability gate; the Jev benchmark is small and templated; none of this yet shows better decisions on real outcomes.